Kling 2.5 Turbo / Text zu Video
Cost-optimized turbo variant of the V2.5 series, reducing generation costs by nearly 30%. Delivers high-speed video generation at 1080p with fewer refinement passes. Ideal for high-volume creative pipelines and rapid social content iteration. Supports text-to-video and image-to-video workflows
Kling V2.5 TurboLow-Latency Text & Image to Video
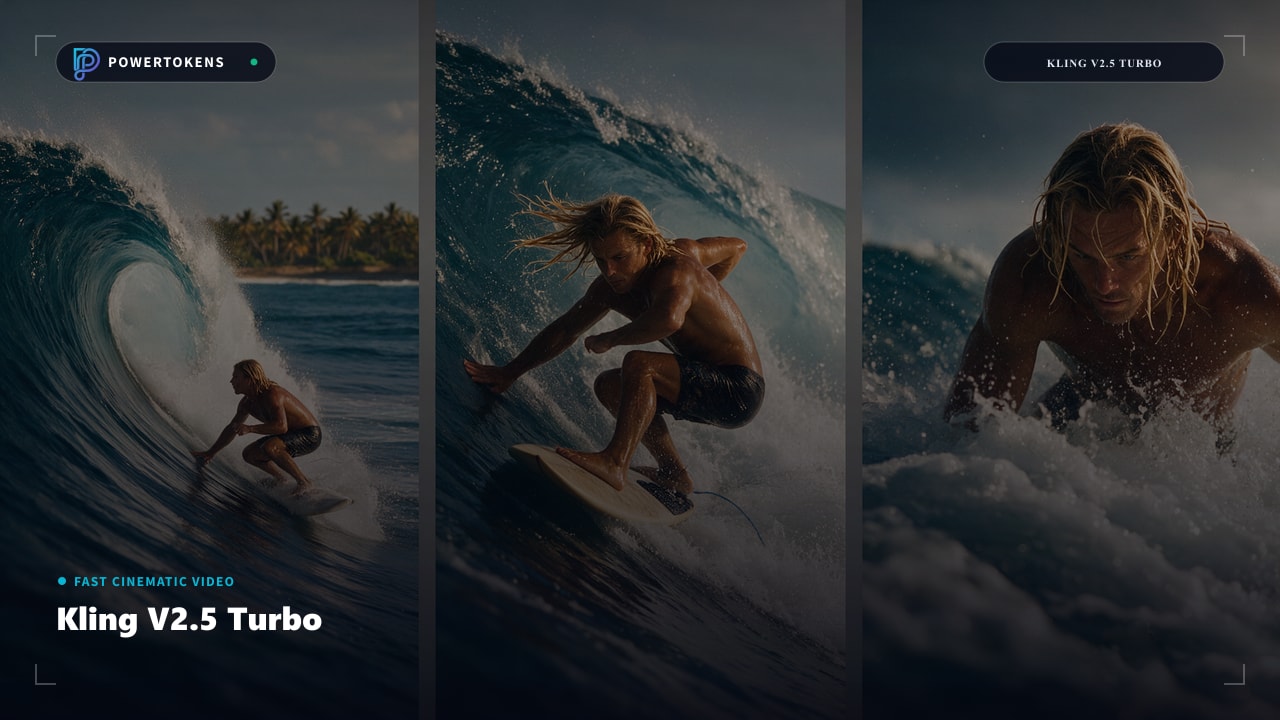
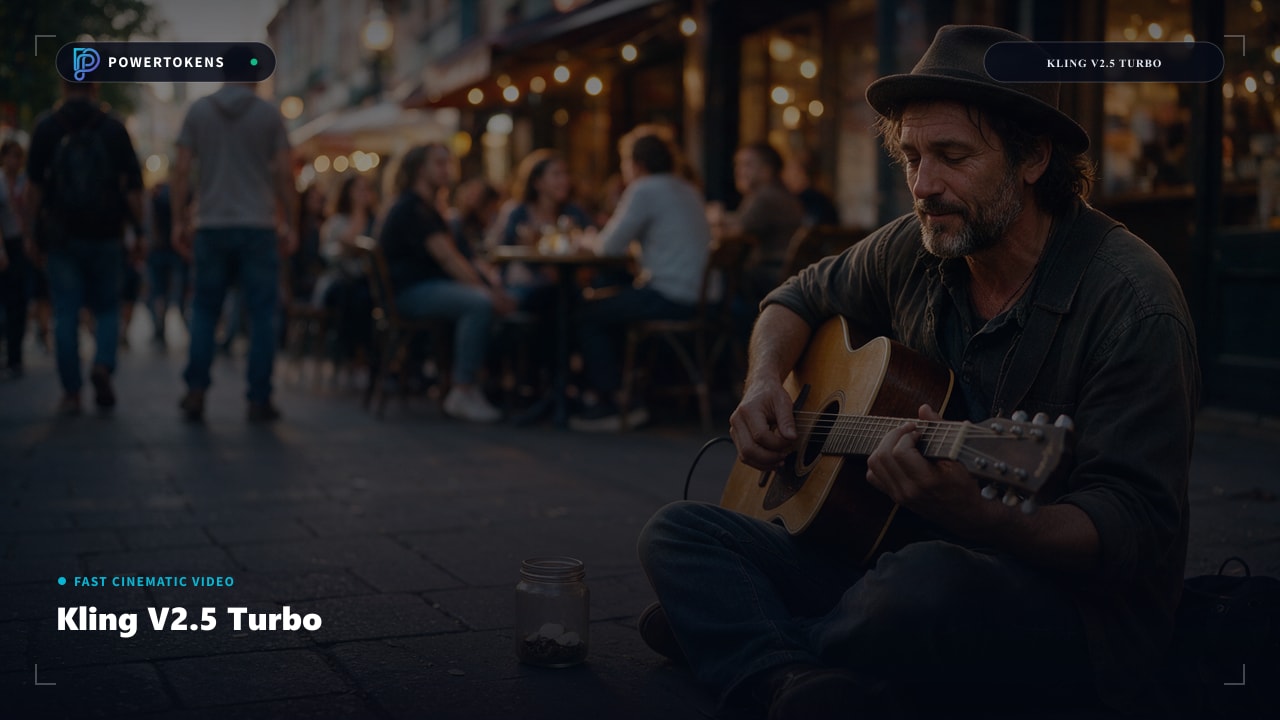
Kling V2.5 Turbo brings rapid video generation with multi-shot control, negative prompts, CFG guidance, optional sound, and image-to-video with end-frame targeting.
At a Glance
Turbo Video Capabilities
Ship cinematic drafts faster without giving up shot-level control.
Image-to-Video with End Frame
Animate a still and optionally pin a tail frame so the motion lands exactly where you want — ideal for product reveals and transitions.
Negative Prompt & CFG
Steer away from unwanted artifacts with negative prompts and dial CFG scale for stronger or softer prompt adherence.
Multi-Shot Storyboarding
Custom or auto multi-shot mode for short narrative arcs without manually splitting requests.
Sound Toggle for Social
Optional synchronized audio when you need a finished social cut; off by default for silent plates.
How It Works
A production-ready path from brief to finished asset.
Pick T2V or I2V
Start from text, or animate a still with optional end-frame targeting.
Steer with CFG & Negative
Raise CFG for stricter prompt following; use negative prompts to remove artifacts.
Choose Mode & Canvas
Standard for speed, Pro for polish. Select 1:1, 16:9, or 9:16.
Ship Variants Fast
Generate multiple seeds/prompts per brief and keep the strongest motion design.
Turbo Production Domains
Where turnaround time unlocks volume.
Rapid Creative Iteration
A/B video variants in minutes, not hours.
Social Vertical Clips
9:16 stories and Reels with optional sound.
Packshot Motion
End-frame product reveals from stills.
Storyboard Previs
Multi-shot previsualization before full renders.
Prompt & Usage Tips
Practical guidance for reliable first-pass results.
Tracking, push-in, orbit — explicit camera language stabilizes Turbo motion.
List only what you must avoid (blurry face, extra limbs) rather than long bans.
I2V with a tail frame is ideal for product reveals and match cuts.
Turbo Quickstart
Text or image to video with guidance controls.
curl -X POST "https://api.powertokens.ai/v1/videos" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "kling-v2-5-turbo",
  "prompt": "Cinematic tracking shot through a neon cyberpunk city in heavy rain.",
  "seconds": "5",
  "size": "1080p",
  "ratio": "16:9",
  "mode": "std",
  "aspect_ratio": "16:9",
  "duration": "5",
  "cfg_scale": 0.5
}'
Technical Specifications
Confirmed parameters and runtime execution protocols.
Preisdetails
Die tatsächliche Abrechnung für dieses Modell wird dynamisch basierend auf den spezifischen Parametern Ihrer API-Anfrage berechnet. Nachfolgend finden Sie die spezifischen Kombinationen und ihre entsprechenden Preise:
| Modalität | Guthaben | Preis (USD) |
|---|---|---|
| 720P5s | 210/ Video | $0.210 |
| 720P10s | 420/ Video | $0.420 |
| 1080P5s | 350/ Video | $0.350 |
| 1080P10s | 700/ Video | $0.700 |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
Kling 3.0 Omni
kling-v3-omni
Flagship unified multimodal model integrating text-to-video, image-to-video, and reference-based generation. Supports up to 15-second cinematic clips with native synchronized audio (dialogue, SFX, BGM). Enables multi-shot control (up to 6 shots) and consistent subject/character preservation across scenes. Pro mode outputs 1080p with enhanced motion realism
kling v3
kling-v3
Next-generation video generation model offering Standard and Pro tiers. Generates 3–15 second clips at up to 1080p resolution from text or image inputs. Features first-frame and last-frame control for precise scene composition. Supports 16:9, 9:16, and 1:1 aspect ratios. Native audio generation available as an optional feature
Kling Video O1
kling-video-o1
World's first unified multimodal video model built on MVL (Multi-modal Visual Language) architecture. Accepts multimodal inputs—text, images, videos, and elements—for all-in-one creation and editing. Supports reference-based generation, start/end frame interpolation, video in/outpainting, stylization, and multi-subject consistency. Generates 3–10s clips with up to 7 reference images
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
Vidu Q4 Preview
viduq4-preview
Next-gen flagship video model preview from Shengshu Technology, focused on expressive character performance, cinematic camera work, and complex VFX . Supports up to 15 reference images (characters, wardrobe, props, scenes) and 3 audio references for voice consistency . Generates up to 16-second clips at 540p–4K with 10-bit color depth
Seedance 2.5
dreamina-seedance-2-5-260628
ByteDance's latest flagship video generation model, built for longer-form storytelling and production-ready output. Generates up to 30 seconds of continuous, cinematic video with native audio sync in a single pass . Accepts up to 50 multimodal references (images, videos, audio, character sheets, storyboards) for precise scene, character, and motion consistency . Features localized region editing to fix specific areas without full regeneration……
Wan 3.0
wan3.0-video
Wan3.0-Video is an all-in-one video generation model unified support for multiple creative capabilities, including reference, editing, replication, and driving. It generates videos up to 30 seconds with omni-modal reference, and can parse files, web pages and complex images. With production-grade character consistency and lifelike visuals and sound, it delivers an immersive audiovisual experience.
Seedance 2.0 Mini
dreamina-seedance-2-0-mini-260615
Lightweight, cost-efficient video model from ByteDance, optimized for speed and high-volume content creation. Supports text-to-video, image-to-video, and reference-based generation with up to 12 references (6 images, 3 audio, 3 video). Delivers faster generation and lower credit consumption than Seedance 2.0, with strong motion quality and character consistency. Ideal for social media content, product videos, AI short dramas, and rapid creative iteration
Frequently Asked Questions
Everything you need to know before integrating this model.
Start Building with Kling V2.5 Turbo Today
Create an account in seconds to receive free test credits. No upfront payment or long-term contract required.