Seedance 1.5 Pro / テキストから動画
Supports generating video with audio from text and images, and supports first and last frames.
Seedance 1.5 ProCinema Video with Synchronized Sound
Seedance 1.5 Pro adds native audio synthesis, adaptive duration (-1), and a draft mode for cheap previews — alongside full text / image / frame conditioning at up to 1080p.
Next-Gen Seedance Capabilities
Audio-aware generation with smarter duration selection and draft previews.
Native Audio Co-Synthesis
Turn on native audio to receive time-aligned environmental sound, foley, and ambience locked to on-screen motion.
Adaptive Duration & Draft Mode
Pass seconds: -1 to let the model choose clip length from prompt pacing, or enable draft mode for faster cheaper previews before final 1080p renders.
First & Last Frame Bridges
Animate between two stills for match cuts, product morphs, and scene transitions that land exactly on the end frame.
Camera Lock for Product Work
Freeze the virtual camera so only the subject moves — cleaner packshot motion and fewer accidental reframes.
How It Works
A production-ready path from brief to finished asset.
Describe Scene + Sound Intent
Write the visual beat and, if useful, the acoustic mood (rain, crowd, engine, silence).
Enable or Disable Audio
Leave native audio on for finished clips, or turn it off when you need a silent plate for post.
Use Adaptive or Fixed Length
Pass -1 to let the model pace the clip, or pin 4–12 seconds for strict editorial timing.
Draft → Final
Preview in draft mode, then re-run at full quality for delivery-ready masters.
Audio-First Production
When the soundtrack is part of the generation, not a post pass.
Social with Sound
Native ambience for TikTok / Reels without a separate audio track.
Product Film Previews
draft mode for cheap client previews before final renders.
Narrative Shorts
Adaptive duration lets the model pace dialogue-friendly clips.
Seamless Scene Chains
Chain clips with continuous ambient sound via last-frame continuation.
Prompt & Usage Tips
Practical guidance for reliable first-pass results.
If you want sound, name environmental cues (rain on metal, distant traffic). Silence should be explicit.
For narrative or dialogue-ish clips, adaptive duration often times cuts better than a fixed number.
Validate motion in draft/silent first, then enable audio for the final pass.
Audio-Enabled Quickstart
Generate clips with synchronized native audio in one request.
curl -X POST "https://api.powertokens.ai/v1/videos" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "seedance-1-5-pro-251215",
  "prompt": "Cinematic tracking shot through a neon cyberpunk city in heavy rain.",
  "seconds": "5",
  "size": "1080p",
  "ratio": "16:9",
  "generate_audio": true
}'
Technical Specifications
Confirmed parameters and runtime execution protocols.
料金詳細
このモデルの実際の課金は、API リクエストで渡される特定のパラメータに基づいて動的に計算されます。以下は具体的な組み合わせとそれに対応する料金です:
| モダリティ | クレジット | 料金 (USD) | ≈秒あたりの価格 (USD) |
|---|---|---|---|
| Without Audio | 1,200/ 1M Tokens | $1.200 | $0.026 |
| With Audio | 2,280/ 1M Tokens | $2.280 | $0.050 |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
Seedance 2.5
dreamina-seedance-2-5-260628
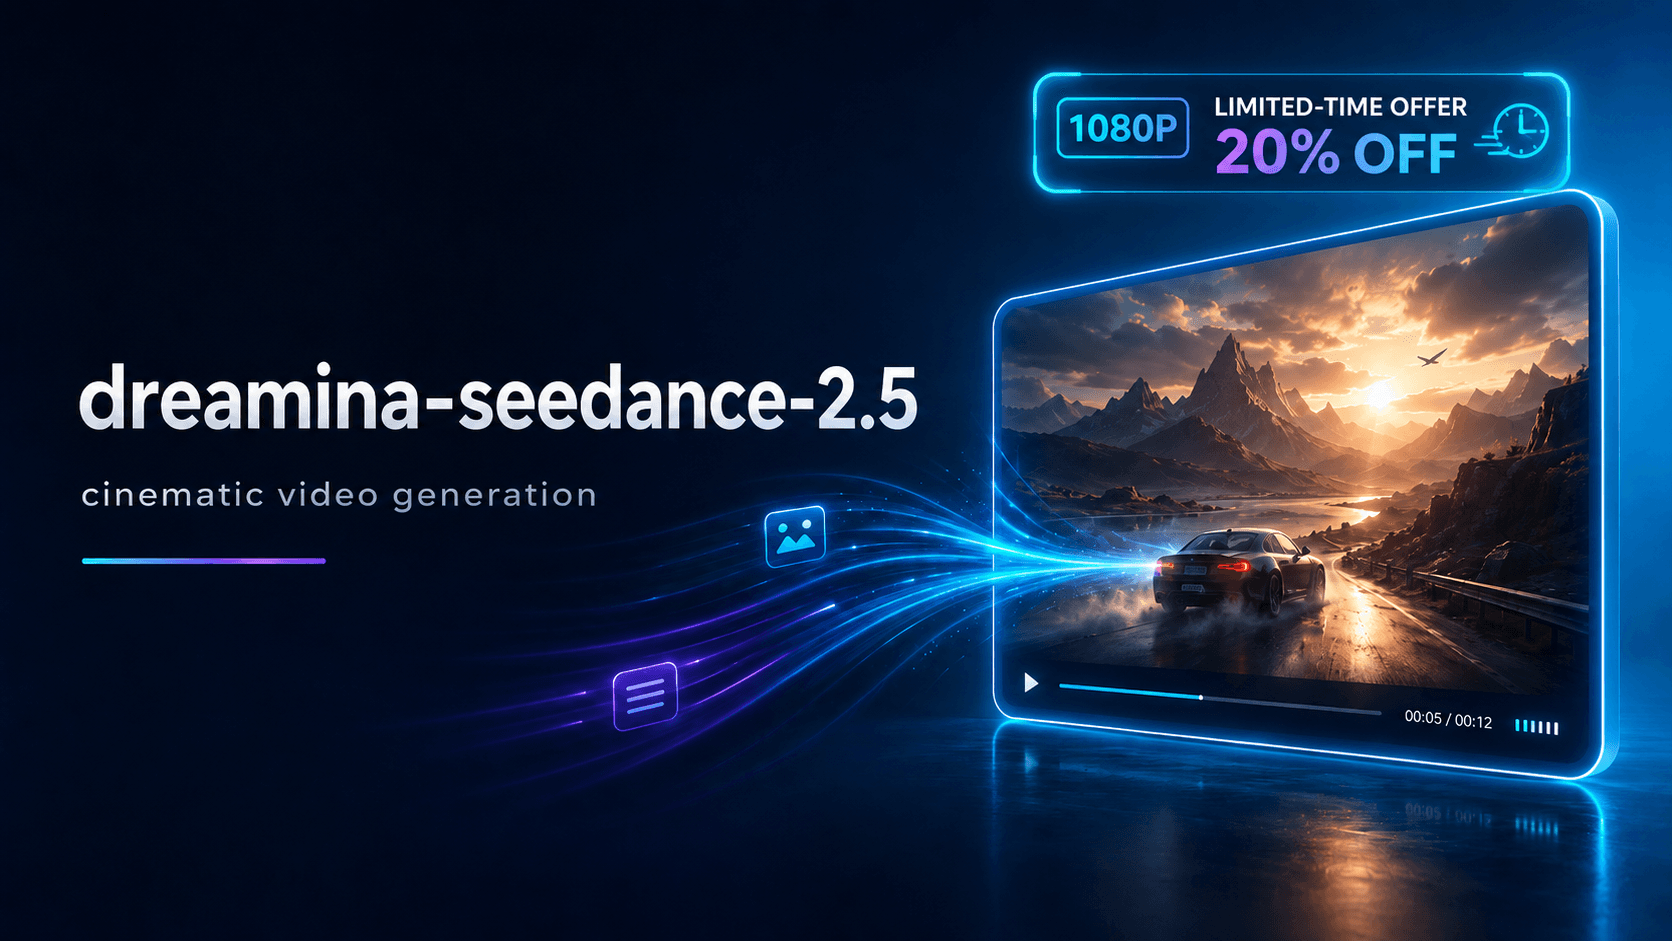
🔥 LIMITED-TIME OFFER: 1080P at 20% OFF! 🔥 ByteDance's latest flagship video generation model, built for longer-form storytelling and production-ready output. Generates up to 30 seconds of continuous, cinematic video with native audio sync in a single pass . Accepts up to 50 multimodal references (images, videos, audio, character sheets, storyboards) for precise scene, character, and motion consistency . Features localized region editing to fix specific areas without full regeneration……
Seedance 2.0 Mini
dreamina-seedance-2-0-mini-260615
Lightweight, cost-efficient video model from ByteDance, optimized for speed and high-volume content creation. Supports text-to-video, image-to-video, and reference-based generation with up to 12 references (6 images, 3 audio, 3 video). Delivers faster generation and lower credit consumption than Seedance 2.0, with strong motion quality and character consistency. Ideal for social media content, product videos, AI short dramas, and rapid creative iteration
Seedance 2.0
dreamina-seedance-2-0-260128
Generate videos from reference images, videos, and audio; edit videos; extend videos; generate videos from start and end frames
Seedance 2.0 Fast
dreamina-seedance-2-0-fast-260128
Generate videos with reference to images/videos/audio, edit videos, extend videos, generate videos from first and last frames
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
Wan 3.0
wan3.0-video
Wan3.0-Video is an all-in-one video generation model unified support for multiple creative capabilities, including reference, editing, replication, and driving. It generates videos up to 30 seconds with omni-modal reference, and can parse files, web pages and complex images. With production-grade character consistency and lifelike visuals and sound, it delivers an immersive audiovisual experience.
Wan 3.0 Prime
wan3.0-video-prime
Wan3.0-Video-Prime is the high-speed video generation model of Wan3.0, with capabilities aligned to the standard version of Wan3.0-Video. It supports four-modal all-in-one reference and generates videos of up to 30 seconds, delivering an immersive audiovisual experience with significantly faster end-to-end generation.
Kling 3.0 Omni
kling-v3-omni
Flagship unified multimodal model integrating text-to-video, image-to-video, and reference-based generation. Supports up to 15-second cinematic clips with native synchronized audio (dialogue, SFX, BGM). Enables multi-shot control (up to 6 shots) and consistent subject/character preservation across scenes. Pro mode outputs 1080p with enhanced motion realism
kling v3
kling-v3
Next-generation video generation model offering Standard and Pro tiers. Generates 3–15 second clips at up to 1080p resolution from text or image inputs. Features first-frame and last-frame control for precise scene composition. Supports 16:9, 9:16, and 1:1 aspect ratios. Native audio generation available as an optional feature
Frequently Asked Questions
Everything you need to know before integrating this model.
Start Building with Seedance 1.5 Pro Today
Create an account in seconds to receive 100 free credits and start generating immediately. No credit card or upfront contract required.