Kling Video O1 / 비디오 생성
World's first unified multimodal video model built on MVL (Multi-modal Visual Language) architecture. Accepts multimodal inputs—text, images, videos, and elements—for all-in-one creation and editing. Supports reference-based generation, start/end frame interpolation, video in/outpainting, stylization, and multi-subject consistency. Generates 3–10s clips with up to 7 reference images
Kling Video O1Omni Video with Multi-Shot Story Control
Kling Video O1 unifies text, image, and video references into cinematic multi-shot clips — with optional sound, Pro quality mode, and 3–10 second durations.
Omni Storytelling Architecture
Blend prompts, stills, and motion references into one coherent multi-shot narrative.
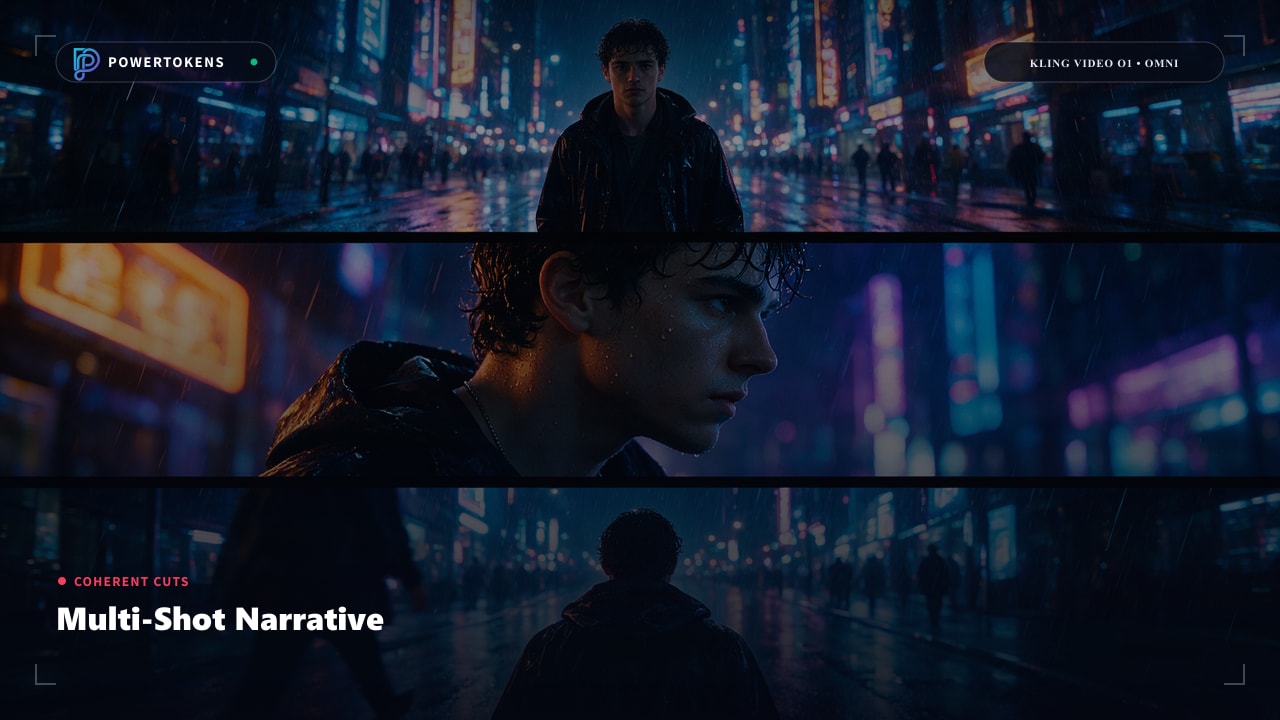
Multi-Shot Story Control
Write custom shot lists or let the model storyboard automatically. Each shot stays coherent across cuts and camera changes.
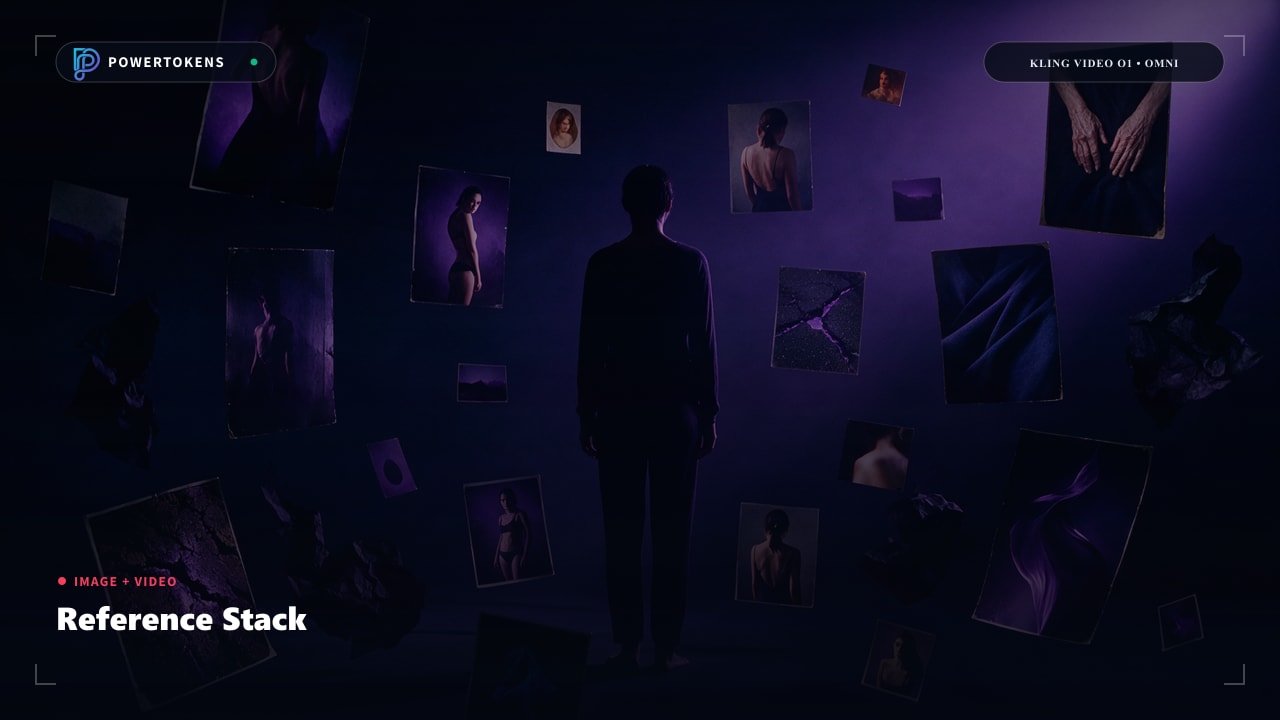
Multimodal Reference Input
Condition on still images and existing video clips together so subject identity, lighting, and motion style carry through the generation.
Optional Synchronized Sound
Enable native sound for finished social cuts, or keep it off when you will score the clip in post.
Pro Mode Fidelity
Default Pro mode prioritizes temporal coherence and material detail for hero placements; Standard is available for drafts.
How It Works
A production-ready path from brief to finished asset.
Assemble References
Collect stills and optional motion references that define subject identity and style.
Outline the Story Beats
Write custom shot prompts or let auto mode structure the narrative arc.
Set Canvas & Sound
Choose 1:1 / 16:9 / 9:16, duration, Pro mode, and whether synchronized sound is needed.
Generate & Chain
Pull the finished multi-shot clip and chain further shots with consistent references.
Cinematic Omni Domains
Where multimodal storytelling replaces multi-tool pipelines.
Brand Story Shorts
Multi-shot narrative ads from stills plus a brief.
Character Episodes
Keep persona consistent across sequential scenes.
Product Demo Films
Animate packshots with optional synchronized sound.
Social Series
9:16 vertical multi-beat clips for Reels and TikTok.
Prompt & Usage Tips
Practical guidance for reliable first-pass results.
In multi-shot mode, write motion per shot instead of one long paragraph.
A clear front-lit subject still beats text-only identity descriptions.
Leave sound off for plates you will score externally; enable it for finished social cuts.
Omni Video Quickstart
Generate multi-shot clips with references and optional sound.
curl -X POST "https://api.powertokens.ai/v1/videos" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "kling-video-o1",
  "prompt": "Cinematic tracking shot through a neon cyberpunk city in heavy rain.",
  "seconds": "5",
  "size": "1080p",
  "ratio": "16:9",
  "mode": "pro",
  "aspect_ratio": "16:9",
  "duration": "5",
  "sound": "on"
}'
Technical Specifications
Confirmed parameters and runtime execution protocols.
가격 상세
이 모델의 실제 요금은 API 요청에서 전달된 특정 매개변수를 기반으로 동적으로 계산됩니다. 아래는 구체적인 조합과 해당 가격입니다:
| 모달리티 | 크레딧 | 가격 (USD) |
|---|---|---|
| 720PWithout Video | 84/ Second | $0.084 |
| 720PWith Video | 126/ Second | $0.126 |
| 1080PWithout Video | 112/ Second | $0.112 |
| 1080PWith Video | 168/ Second | $0.168 |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
Kling 3.0 Omni
kling-v3-omni
Flagship unified multimodal model integrating text-to-video, image-to-video, and reference-based generation. Supports up to 15-second cinematic clips with native synchronized audio (dialogue, SFX, BGM). Enables multi-shot control (up to 6 shots) and consistent subject/character preservation across scenes. Pro mode outputs 1080p with enhanced motion realism
kling v3
kling-v3
Next-generation video generation model offering Standard and Pro tiers. Generates 3–15 second clips at up to 1080p resolution from text or image inputs. Features first-frame and last-frame control for precise scene composition. Supports 16:9, 9:16, and 1:1 aspect ratios. Native audio generation available as an optional feature
Kling 2.5 Turbo
kling-v2-5-turbo
Cost-optimized turbo variant of the V2.5 series, reducing generation costs by nearly 30%. Delivers high-speed video generation at 1080p with fewer refinement passes. Ideal for high-volume creative pipelines and rapid social content iteration. Supports text-to-video and image-to-video workflows
Kling 2.1 Master
kling-v2-1-master
Premium Master edition of the V2.1 series. Generates 5-second and 10-second videos at 1080p from text or image inputs. Offers superior motion dynamics, stronger prompt adherence, and enhanced subject consistency. Features first-frame and last-frame control for guided composition
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
Seedance 2.5
dreamina-seedance-2-5-260628
🔥 LIMITED-TIME OFFER: 1080P at 20% OFF! 🔥 ByteDance's latest flagship video generation model, built for longer-form storytelling and production-ready output. Generates up to 30 seconds of continuous, cinematic video with native audio sync in a single pass . Accepts up to 50 multimodal references (images, videos, audio, character sheets, storyboards) for precise scene, character, and motion consistency . Features localized region editing to fix specific areas without full regeneration……
Wan 3.0
wan3.0-video
Wan3.0-Video is an all-in-one video generation model unified support for multiple creative capabilities, including reference, editing, replication, and driving. It generates videos up to 30 seconds with omni-modal reference, and can parse files, web pages and complex images. With production-grade character consistency and lifelike visuals and sound, it delivers an immersive audiovisual experience.
Seedance 2.0 Mini
dreamina-seedance-2-0-mini-260615
Lightweight, cost-efficient video model from ByteDance, optimized for speed and high-volume content creation. Supports text-to-video, image-to-video, and reference-based generation with up to 12 references (6 images, 3 audio, 3 video). Delivers faster generation and lower credit consumption than Seedance 2.0, with strong motion quality and character consistency. Ideal for social media content, product videos, AI short dramas, and rapid creative iteration
Seedance 2.0
dreamina-seedance-2-0-260128
Generate videos from reference images, videos, and audio; edit videos; extend videos; generate videos from start and end frames
Frequently Asked Questions
Everything you need to know before integrating this model.
Start Building with Kling Video O1 Today
Create an account in seconds to receive 100 free credits and start generating immediately. No credit card or upfront contract required.