wan2.7-image / 텍스트로 이미지
Alibaba's unified image generation and editing model supporting text-to-image, sequential image generation, instruction-based editing, multi-reference generation (up to 9 images), and interactive bbox editing. Features precise "face sculpting" for diverse, non-generic portraits and a "palette" function for exact Hex color control. Renders up to 3K tokens of long-form text (12 languages) at print quality. Generates up to 12 images per run
Wan 2.7 ImageHigh-Fidelity Text-to-Image Generation
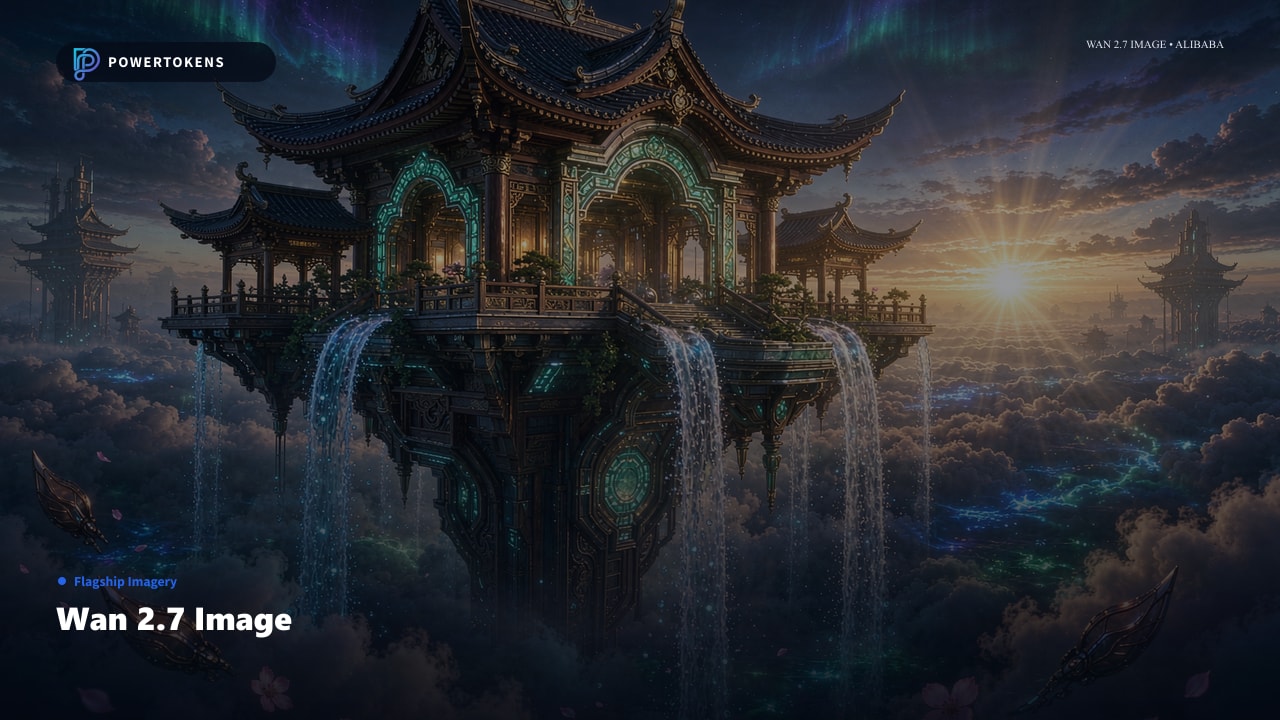
Wan 2.7 Image delivers fast, high-fidelity visual generation with deep prompt comprehension, photorealistic lighting, and flexible aesthetic stylization.
At a Glance
Wan 2.7 Image Capabilities
Production-ready visual synthesis for creative workflows.
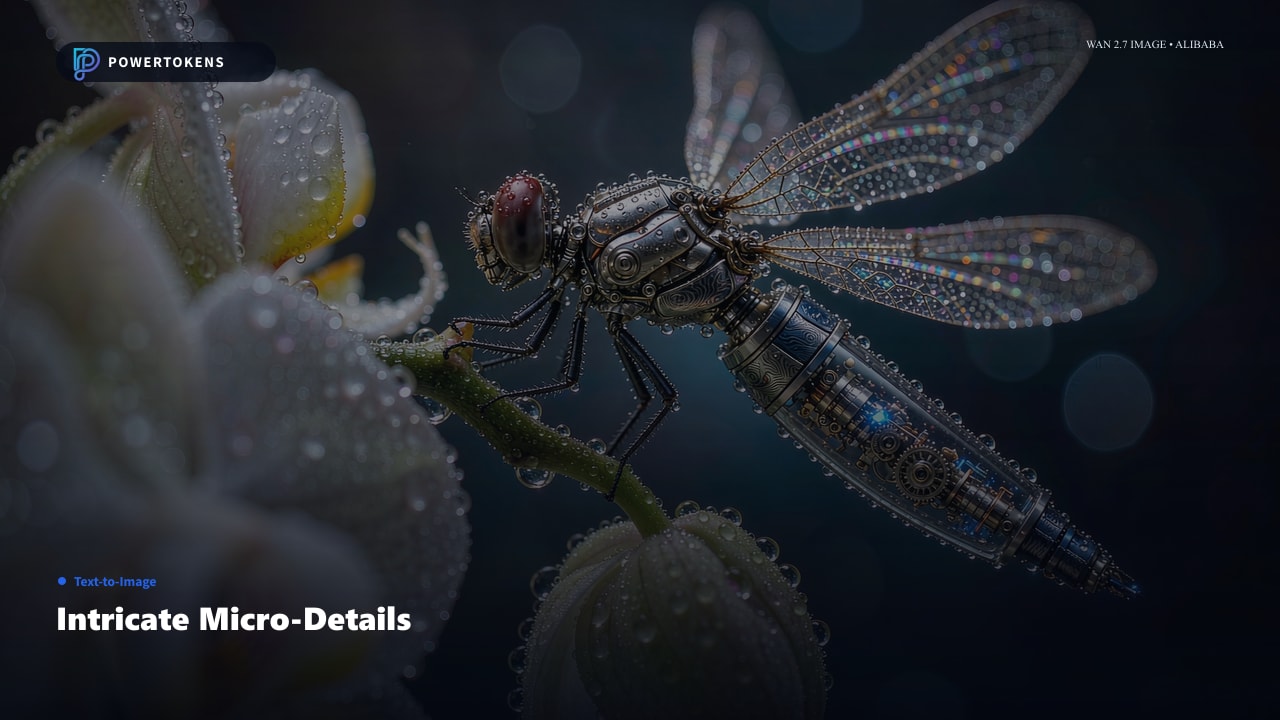
Intricate Micro-Details
Render micro-textures, intricate mechanical structures, and hyper-detailed subjects with sharp geometric precision.
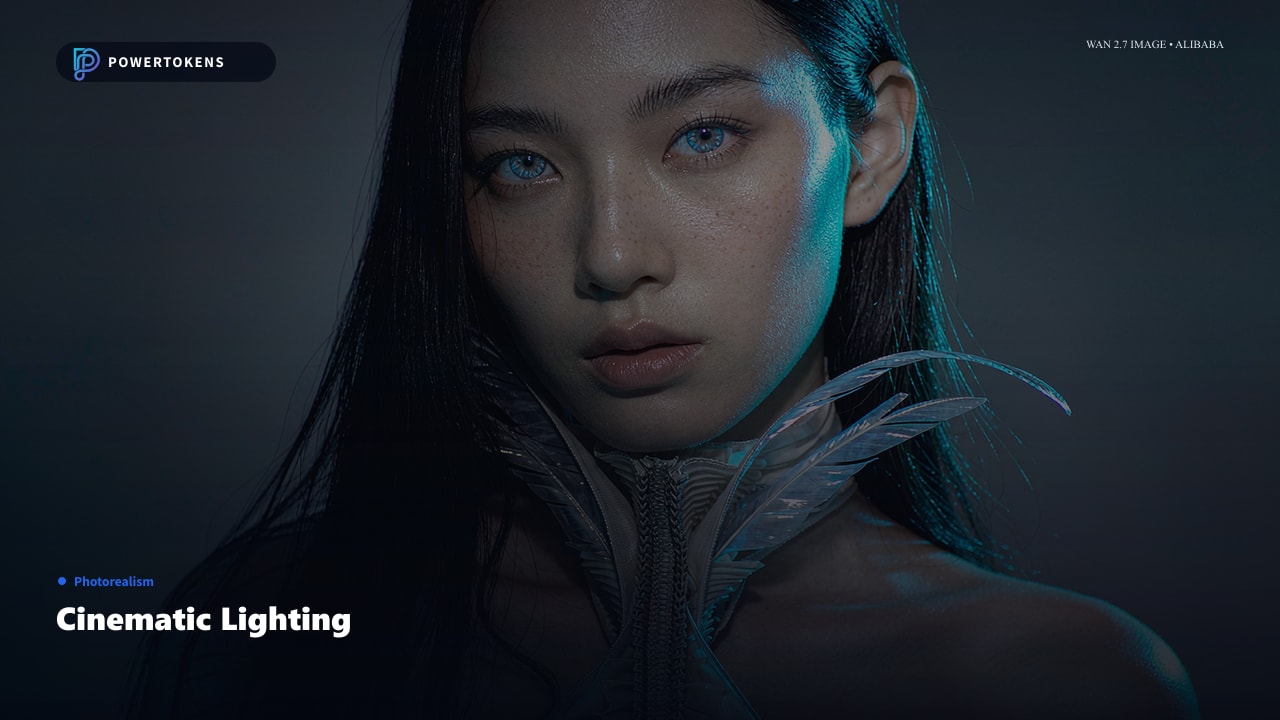
Cinematic Studio Lighting
Accurate ray tracing, volumetric glow, and subsurface scattering for dramatic studio portraits and rich scenes.
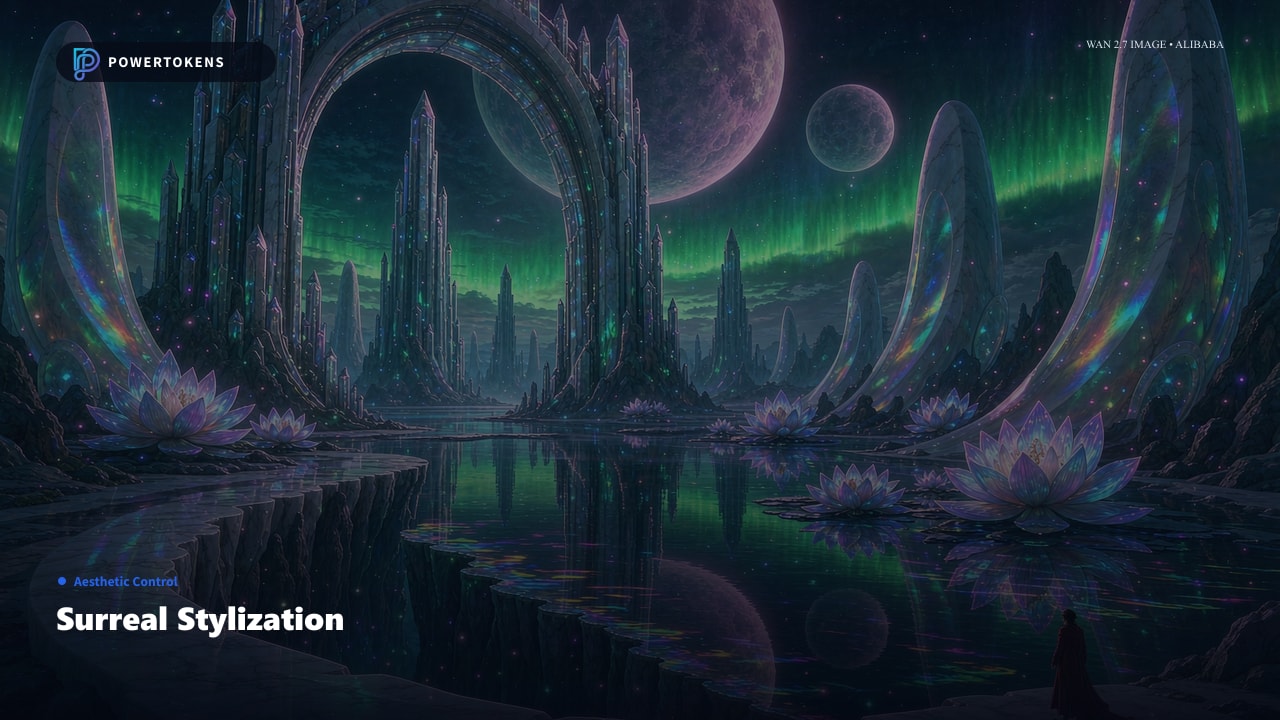
Surreal Worldbuilding & Stylization
Translate abstract creative briefs into rich, coherent surreal landscapes and distinctive visual worlds.
How It Works
From natural text prompt to production-grade imagery.
Compose Prompt
Describe your scene, subject, aesthetic style, and atmospheric lighting in natural language.
Configure Options
Set output aspect ratio, seed, and optional negative prompts to fine-tune results.
Generate & Iterate
Synthesize images rapidly via API or Playground with sub-second feedback.
Production Export
Obtain high-res image URLs ready for design workflows and creative assets.
Wan 2.7 Image Domains
Where high-fidelity text-to-image synthesis accelerates creative production.
Concept Art
Quickly ideate high-res visual concepts, characters, and futuristic environments.
Commercial Visuals
Photorealistic key visuals and campaign assets with studio-grade lighting.
Digital Worldbuilding
Vivid surreal landscapes and atmospheric backdrops for media production.
Editorial Illustrations
Distinctive visual storytelling with expressive artistic stylization.
Prompt Tips
Practical recommendations for superior Wan 2.7 Image results.
Mention specific light sources like "volumetric rim lighting", "dramatic side light", or "soft diffused morning glow".
Specify focal length, angle, and framing (e.g., "cinematic wide angle", "macro close-up", "low-angle perspective").
Hold the seed constant while tweaking prompts to explore subtle lighting and styling variations.
Wan 2.7 Image Quickstart
Standard text-to-image API generation.
curl -X POST "https://api.powertokens.ai/v1/images/generations" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type": "application/json" \
  -d '{
  "model": "wan2.7-image",
  "prompt": "A breathtaking cyberpunk city with neon towers, photorealistic lighting.",
  "size": "2K",
  "response_format": "url",
  "watermark": false
}'
Technical Specifications
Confirmed parameters and runtime execution protocols.
가격 상세
이 모델의 실제 요금은 API 요청에서 전달된 특정 매개변수를 기반으로 동적으로 계산됩니다. 아래는 구체적인 조합과 해당 가격입니다:
| 모달리티 | 크레딧 | 가격 (USD) |
|---|---|---|
| Standard | 30/ Image | $0.030 |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
Wan 2.7 Image Pro
wan2.7-image-pro
Wan2.7–image-pro,supports text to image, text/image to sequential images, image editing, multi-image reference generation, and interactive editing. Delivers enhanced performance in text rendering, subject consistency, and complex instruction following.
Qwen Image 2.0 Pro
qwen-image-2.0-pro
The full-featured Qwen-Image-2.0 series models integrate image generation and image editing, offering enhanced text rendering with support for 1,000-token prompts, more refined realistic textures, detailed depiction of photorealistic scenes, and stronger semantic adherence. The full-featured version delivers the strongest text rendering and most lifelike textures in the 2.0 series.
Qwen Image 3.0 Pro
qwen-image-3.0-pro
Professional-grade image generation and editing model. Supports text-to-image and image-to-image workflows with precise rendering of text as small as 10px. Generates complex layouts—newspapers, storyboards, menus, exam papers—in a single pass. Native 12-language rendering with rich world knowledge. Input up to 4.5K tokens
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
Seedream 5.0
seedream-5-0-260128
Supports text, single-image and multi-image inputs, and enables the generation of image sets
Kling Image O1
kling-image-o1
Advanced image generation model from the Kling O1 family. Supports text-to-image and image-to-image workflows with deep semantic understanding. Features character/subject consistency across generations, multi-reference input (up to 7 images), and intelligent aspect ratio adaptation. Professional-grade output suitable for commercial creative pipelines
MiniMax Image-01
image-01
MiniMax’s first text-to-image model with subject reference support. Delivers high-fidelity visuals, detailed lighting, and complex scene composition. Generates realistic human/object renders with natural textures, ideal for concept art, product visualization, and creative design.
Seedream 4.5
seedream-4-5-251128
Supports text, single-image, and multi-image input, and enables batch image generation.
Frequently Asked Questions
Everything you need to know before integrating this model.
Start Building with Wan 2.7 Image Today
Create an account in seconds to receive free test credits. No upfront payment or long-term contract required.