Seed 2.0 Pro / 对话
Focused on long-chain reasoning and stability in complex task execution, designed for complex real-world business scenarios.
Playground 对话
与 AI 模型开启对话,您可以询问任何问题。
AI 生成结果的准确性可能有所不同。
Seed 2.0 ProProduction Chat with Deep Thinking
Seed 2.0 Pro combines configurable deep thinking with adjustable reasoning depth, token probability signals, stop sequences, and parallel tool calling.
At a Glance
Reasoning-Aware Chat Architecture
Tune depth of thought per request without changing models.
Configurable Thinking Depth
Toggle deep thinking on or off and dial reasoning depth from Minimal to High based on task complexity and latency budget.
Production Tool Stack
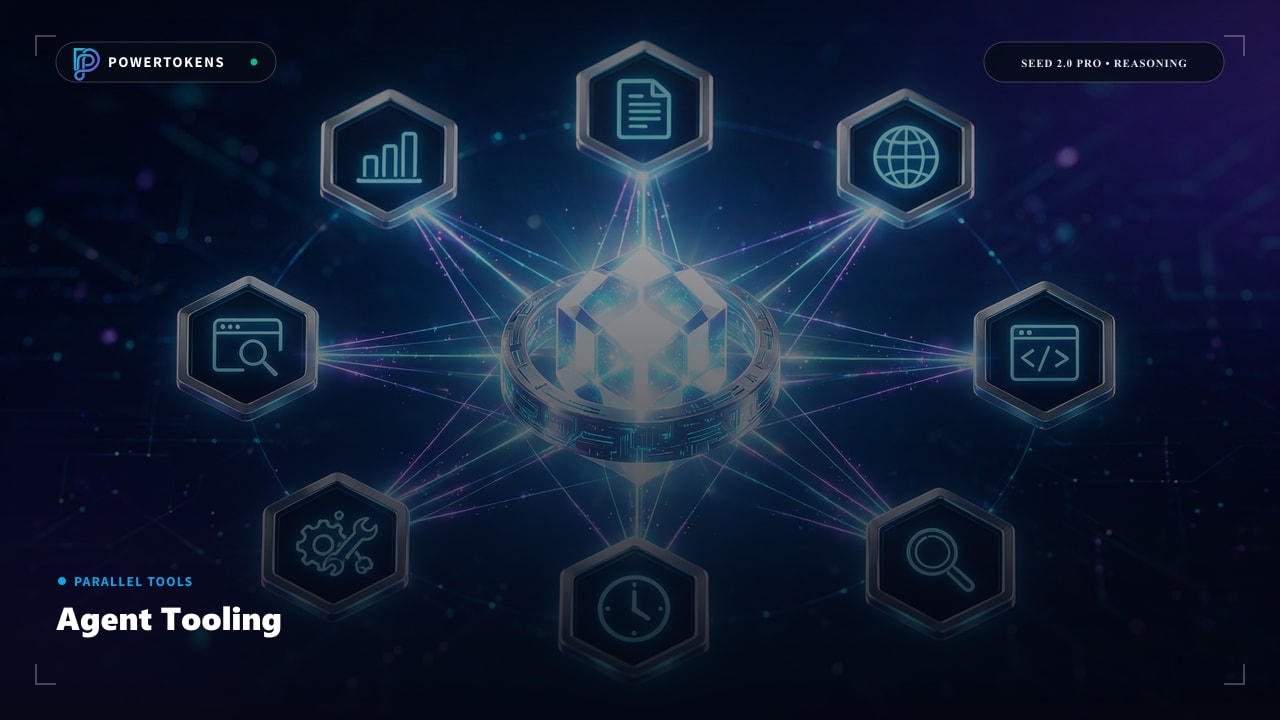
Parallel tool calling, stop sequences, and logprobs for evaluation and agent confidence scoring.
Stop Sequences & Bounds
Constrain generation with stop sequences so outputs fit parsers, UIs, and downstream automations cleanly.
Enterprise Sampling Controls
Temperature, top-p, and frequency/presence penalties give product teams fine-grained tone and diversity control.
How It Works
A production-ready path from brief to finished asset.
Pick Reasoning Depth
Minimal for speed, Medium for everyday analysis, High for multi-step proofs.
Stream or Wait
Stream for interactive UIs; single-shot for batch evaluation harnesses.
Call Tools in Parallel
Declare tools and allow parallel calls when independent lookups can fan out.
Score with Logprobs
Use logprobs and top-logprobs for confidence scoring and quality gates.
Enterprise Chat Domains
Where configurable reasoning improves quality.
Complex Analysis
High reasoning depth for multi-step analysis tasks.
Agent Workflows
Parallel tools with calibrated confidence via logprobs.
Customer Support
Minimal effort for fast, factual support replies.
Code Assistance
Medium/high effort for refactoring and debugging.
Prompt & Usage Tips
Practical guidance for reliable first-pass results.
Specify the artifact you want (JSON schema, ranked list, proof steps).
Do not burn High effort on classification. Minimal effort is enough for many ops tasks.
Describe tool side effects clearly so parallel calls stay safe and predictable.
Reasoning Quickstart
Enable thinking and set effort for complex tasks.
curl -X POST "https://api.powertokens.ai/v1/chat/completions" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "seed-2-0-pro-260328",
    "messages": [
      {"role": "user", "content": "Prove that the sum of two even numbers is always even."}
    ],
    "stream": true,
    "temperature": 0.7
  }'
Technical Specifications
Confirmed parameters and runtime execution protocols.
价格详情
此模型的实际计费根据您在 API 请求中传入的具体参数动态计算。以下是具体的组合及其对应的价格:
| 模态 | 输入积分 | 输出积分 | 输入价格 | 输出价格 | 隐式缓存命中 | 显式缓存命中 | 创建缓存 |
|---|---|---|---|---|---|---|---|
| 0 - 128K | 475/ 1M Tokens | 2,850/ 1M Tokens | $0.475 | $2.850 | $0.100 100/ 1M Tokens | -- | -- |
| 128K - 256K | 950/ 1M Tokens | 5,700/ 1M Tokens | $0.950 | $5.700 | $0.200 200/ 1M Tokens | -- | -- |
Models from the Same Channel
Explore complementary models and alternative versions from the same provider channel.
Recommended Related Models
Explore complementary video and multimodal models with your unified API key.
GLM-5.3
glm-5.3
Zhipu AI's flagship text model optimized for complex software engineering and long-horizon Agent tasks. Features a 1M-token context window with mandatory reasoning (3 levels: low/high/max). Coding capability improved 50% over GLM-5.2 on Z.ai Code Bench; scores SOTA on Terminal Bench 3.0. Excels in cybersecurity tasks (cyber vulnerability discovery)
MiniMax-M3.1-Flash
MiniMax-M3.1-Flash
Next-gen efficiency-focused multimodal model (428B MoE) for agentic workflows, coding, and computer use . Features a 1M-token context window and tunable thinking depth (low–max) . Scores 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, and 82% on CyberGym, while delivering 200+ TPS output speed at 70% lower agent-task cost than its predecessor
MiMo-V2.6-Pro-UltraSpeed
mimo-v2.6-pro-ultraspeed
High-speed edition of Xiaomi's 1T-parameter flagship, delivering roughly 10x output speed while matching the original model's quality. Features a 1M-token context window and native multimodal input (text, image, video, audio). Optimized for latency-sensitive agentic workflows, coding, and long-horizon tasks
GLM-5.3 Flash
glm-5.3-flash
Z.ai's native multimodal model (320B-A18B) with text, image, video, and file input. Features hybrid sparse + linear attention, reducing attention compute 3x and KV cache 4.4x vs. GLM-5.3. Scores 57 on Artificial Analysis Intelligence Index—matching Claude Opus 4.8—with 1M context and 128K max output. Excels in agentic coding, vision-based Computer Use, and CAD reproduction
Frequently Asked Questions
Everything you need to know before integrating this model.
Start Building with Seed 2.0 Pro Today
Create an account in seconds to receive free test credits. No upfront payment or long-term contract required.